Looking for the latest information on Adamatch Explained? We've gathered comprehensive data, records, and insights about Adamatch Explained.
Core Information
Explore the primary sources for Adamatch Explained.
Recent Updates
Stay updated on Adamatch Explained's latest milestones.
Adversarial Discriminative Domain Adaptation (ADDA) Paper Explained
Adam Optimiser Explained from Scratch: Why It Beats SGD for Deep Learning
Standing the test of time: Adam and Optimizers Explained
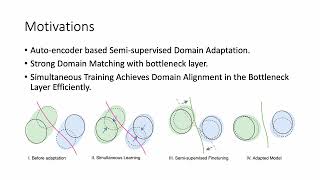
Semi-Supervised Domain Adaptation with Auto-Encoder via Simultaneous Learning
ADAM Optimization Algorithm Explained Visually | Deep Learning #13
Adaptive Optimizers explained: AdaGrad → RMSProp → Adam
83 - SoFA: Source-data-free Feature Alignment for Unsupervised Domain Adaptation
[CVPR 2023] Semi-Supervised Domain Adaptation with Source Label Adaptation
Divide and Contrast Explained!
Claude Solved a 27-Year NSA Mystery in Half an Hour
AD4M Explained in 12 minutes
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 19, 2026
Conclusion
For 2026, Adamatch Explained remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
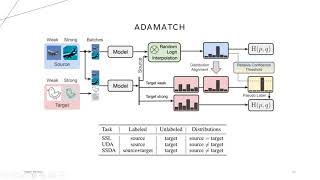
Semi-Supervised Learning algorithms can be applied out-of-the-box for Domain Adaptation! This video explains the extensions to ... Part 6/6 of Parameter-Efficient & Memory-Efficient LLM Training. Series playlist: ... What do compressed neural networks forget? This paper shows how to utilize these lessons to improve contrastive ... We are exploring how to navigate the loss surface, specifically focusing on engineering the Adam optimizer for non-stationary ... In this video I walk through four of the most used optimizers in machine learning. Authors: Rahman, Md Mahmudur*; Panda, Rameswar; Alam, Mohammad Arif Ul Description: We present a new semi-supervised ... In this video, you'll learn how Adam makes gradient descent faster, smoother, and more reliable by combining the strengths of ... From a 1951 statistics problem to the engine behind modern AI — SGD doesn't compute the perfect direction, it guesses, stumbles ... Project page: github.com/chu0802/SLA Paper: arxiv.org/pdf/2302.02335.pdf. This is an interesting strategy to utilize clustering in the contrastive self-supervised learning pipeline. The three-stage pipeline ... Free weekly AI × math briefing → ademb10.com/?ref=nsa-seeds The elliptic curves behind much of the web's certificates ... AD4M is an engine for decentralised social networks and collaboration software - an agent-centric spanning layer extending the ...