Introduction on Code Optimized Reasoning Traning W Ci
Looking for the latest information on Code Optimized Reasoning Traning W Ci? We've compiled comprehensive data, records, and insights about Code Optimized Reasoning Traning W Ci.
Core Information
Explore the key sources for Code Optimized Reasoning Traning W Ci.
History
Stay updated on Code Optimized Reasoning Traning W Ci's latest milestones.
Competitive Programming with Large Reasoning Models
RL With Verifiable Rewards: The Math Behind Reasoning Models
The Future of AI Coding Models: WizardCoder + Evol-Instruct Deep Dive
GLM-4.5: A 355B Parameter MoE Model with Advanced Reasoning & Coding
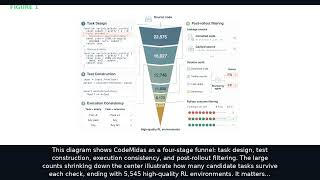
CodeMidas: Scaling Agentic Coding RL Environments from Code Itself
Understanding Reasoning Models | Build a Reasoning Model (From Scratch)
GPT-5.1 CRUSHES Codeforces: How Adaptive Reasoning Changes EVERYTHING for Devs!
Agentic Code Reasoning
The art of training a good (reasoning) language model
Build A Reasoning Model From Scratch 1: Motivation & Code Setup
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 17, 2026
Future Outlook
For 2026, Code Optimized Reasoning Traning W Ci remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
NEW Solution for failing Chain-of-Thoughts (CoT): Hint Engineering for To address this, the authors introduce CoRT ( This research paper assesses the performance of OpenAI's large language models (LLMs) on competitive programming tasks. What happens when the reward cannot be fooled? This 29-minute, math-first video builds reinforcement learning with verifiable ... For more information about Stanford's graduate programs, visit: online.stanford.edu/graduate-education November 7, 2025 ... What if we could teach AI to write In this video, we explore the GLM-4.5 series, including the flagship 355B parameter GLM-4.5 and the efficient 106B parameter ... Today's standout paper is CodeMidas, which tackles a big bottleneck in OpenAI's GPT-5.1 isn't just an upgrade—it's a revolution in Why are some models that are totally exceptional on every benchmark a total flop in normal use? This is a question I was hinting ... This video explains the relationship between conventional LLMs and