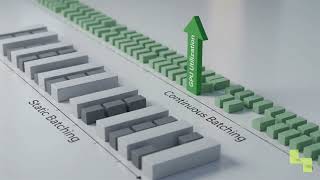
Looking for the latest information on Continuous Batching Ai S Engine? We've gathered comprehensive data, records, and insights about Continuous Batching Ai S Engine.
Important Facts
Explore the key sources for Continuous Batching Ai S Engine.
Recent Updates
Stay updated on Continuous Batching Ai S Engine's newest achievements.
Continuous Batching
How to Scale LLM Applications With Continuous Batching!
What Is Continuous Batching Why Your GPU Sits Idle, for Your AI System Design Interview
Continuous Batching in LLMs Explained: Fast LLM Inference & Serving (vLLM, TensorRT-LLM)
vLLM Fully explained page attention & continuous batching in simple way
Paged Attention and Continuous Batching: How vLLM Actually Works
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
Continuous Batching - How AI APIs Serve Thousands of Users at Once
Continuous Batching Explained: Iteration-Level Scheduling in vLLM (Orca Paper)
Continuous Batching How AI APIs Serve Thousands of Users at Once
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 21, 2026
Final Thoughts
For 2026, Continuous Batching Ai S Engine remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
The provided technical article outlines the fundamental mechanisms and optimization techniques necessary to understand and ... Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... How does ONE GPU serve hundreds of people at once? This is the full story of vLLM, built from zero: why generating text is a ... A serving technique where new requests are added to an in-progress If you want to deploy an LLM endpoint, it is critical to think about how different requests are going to be handled. In typical ... A market stall stamps six name tags at once, and five of the six under the hammers are already finished. In under five minutes, one ... Want to make your Large Language Models (LLMs) run faster and more efficiently? In this video, I explain vLLM — an ... We build up how vLLM serves thousands of users from two pieces of bookkeeping: the scheduler and the KV cache memory ...