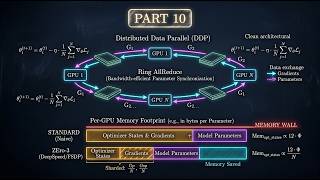
Introduction to Data Parallel To Distributed Data Parallel
Looking for the latest information on Data Parallel To Distributed Data Parallel? We've researched comprehensive data, records, and insights about Data Parallel To Distributed Data Parallel.
Key Details
Explore the primary sources for Data Parallel To Distributed Data Parallel.
Developments
Stay updated on Data Parallel To Distributed Data Parallel's latest milestones.
Multi-GPU Fine-Tuning Made Easy: From Data Parallel to Distributed Data Parallel in 5 lines of code
How Fully Sharded Data Parallel (FSDP) works
Part 1: Welcome to the Distributed Data Parallel (DDP) Tutorial Series
Distributed Data Parallel Explained (Lesson 10)
Task vs. Data Parallelism
Lecture 02 - Data Parallel Programming
Stanford CS149 I Parallel Computing I 2023 I Lecture 8 - Data-Parallel Thinking
Stanford CS149 I 2023 I Lecture 9 - Distributed Data-Parallel Computing Using Spark
Data Parallel Model Lecture 15
Temporal Parallelism and Data Parallelism #TemporalParallelism #DataParallelsim #ParallelComputing
Distributed ML Talk @ UC Berkeley
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 15, 2026
Summary
For 2026, Data Parallel To Distributed Data Parallel remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Discover how DDP harnesses multiple GPUs across machines to handle larger models and datasets, accelerating the training ... In the second video of this series, Suraj Subramanian gently introduces you to what is happening under the hood when you train a ... A complete tutorial on how to train a model on multiple GPUs or multiple servers. I first describe the difference between Learn how to optimize your large language model fine-tuning with multi-GPU support using Hugging Face and Kaggle's free ... In the first video of this series, Suraj Subramanian breaks down why Why does a 70B parameter LLM run fine on a consumer rig, but crash an 80GB Nvidia H100 GPU before training even begins? GPU Computing, Spring 2021, Izzat El Hajj Department of Computer Science American University of Beirut. Producer-consumer locality, RDD abstraction, Spark implementation and scheduling To along with the course, visit the ... Welcome to the video, here we will discuss the concepts of temporal parallelism and Here's a talk I gave to to Machine Learning @ Berkeley Club! We discuss various
What is the most accurate information about Data Parallel To Distributed Data Parallel?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Data Parallel To Distributed Data Parallel.
Why is Data Parallel To Distributed Data Parallel trending right now?
Interest in Data Parallel To Distributed Data Parallel has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Data Parallel To Distributed Data Parallel?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Data Parallel To Distributed Data Parallel updated?
We regularly update our database with the latest information, media, and analysis related to Data Parallel To Distributed Data Parallel.