About of Distributed Training All Reduce Colllective Operations
Looking for the latest information on Distributed Training All Reduce Colllective Operations? We've gathered comprehensive data, records, and insights about Distributed Training All Reduce Colllective Operations.
Key Details
Explore the key sources for Distributed Training All Reduce Colllective Operations.
Developments
Stay updated on Distributed Training All Reduce Colllective Operations's latest milestones.
Stanford CS231N | Spring 2025 | Lecture 11: Large Scale Distributed Training
Distributed Training - All-Gather colllective operations
AllGather | Bruck's algorithm
Collective Operations, Part 1
NCCL Explained: How NVIDIA's GPU Communication Library Powers Distributed Deep Learning
NSDI '23 - TACCL: Guiding Collective Algorithm Synthesis using Communication Sketches
169 Collective Operations, Part 1
🤗 Accelerate DataLoaders during Distributed Training: How Do They Work
Distributed and Stable LLM Training on a Large-Scale Cluster
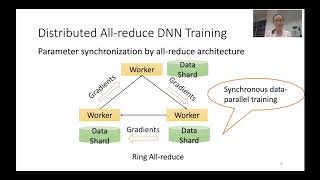
Preemptive All-reduce Scheduling for Expediting Distributed DNN Training
Distributed Data Parallel (DDP) with PyTorch: complete tutorial with cloud infrastructure and code
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 22, 2026
Summary
For 2026, Distributed Training All Reduce Colllective Operations remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Google Cloud Developer Advocate Nikita Namjoshi introduces how On Hopsworks, learn how to: 1. train a TensorFlow model using many GPUs using Hopsworks 2. how to use CollectiveAllReduce ... This video is part of the Udacity course "High Performance Computing". Watch the full course at ... In this video, we break down NCCL (NVIDIA In this tutorial we will learn how Accelerate's DataLoaders work during Third session from the webinar series jointly organized by and Pune, focused on Yixin Bao, Yanghua Peng, Yangrui Chen, Chuan Wu. "Preemptive A complete tutorial on how to train a model on multiple GPUs or multiple servers. I first describe the difference between Data ...
Distributed Training All Reduce Colllective Operations.pdf
What is the most accurate information about Distributed Training All Reduce Colllective Operations?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Distributed Training All Reduce Colllective Operations.
Why is Distributed Training All Reduce Colllective Operations trending right now?
Interest in Distributed Training All Reduce Colllective Operations has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Distributed Training All Reduce Colllective Operations?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Distributed Training All Reduce Colllective Operations updated?
We regularly update our database with the latest information, media, and analysis related to Distributed Training All Reduce Colllective Operations.