Overview to Llm Compression Explained Quantization Pruning For Faster Ai
Looking for the latest information on Llm Compression Explained Quantization Pruning For Faster Ai? We've researched comprehensive data, records, and insights about Llm Compression Explained Quantization Pruning For Faster Ai.
Main Features
Explore the primary sources for Llm Compression Explained Quantization Pruning For Faster Ai.
Recent Updates
Stay updated on Llm Compression Explained Quantization Pruning For Faster Ai's newest achievements.
Model Compression Explained: Making AI Smaller & Faster 🚀
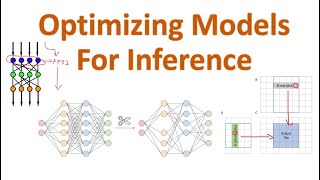
Quantization vs Pruning vs Distillation: Optimizing NNs for Inference
Optimize Your AI - Quantization Explained
Compressing Neural Networks for Embedded AI: Pruning, Projection, and Quantization
ML Model Optimization: Quantization & Pruning Explained
How LLMs survive in low precision | Quantization Fundamentals
Understanding Model Quantization and Distillation in LLMs
What is LLM quantization
Shrink Your LLMs: Master Quantization & Pruning
How Do You Make an LLM 2x Faster Without Quantization or Pruning | AI Interview Question
Compressing Large Language Models (LLMs) | w/ Python Code
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 19, 2026
Final Thoughts
For 2026, Llm Compression Explained Quantization Pruning For Faster Ai remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Video Description Tired of slow, expensive Ready to become a certified watsonx Try Voice Writer - speak your thoughts and let Learn how to optimize your machine learning models using In this video, we discuss the fundamentals of model In this video we define the basics of Stop wasting VRAM and compute! Learn how to shrink your models without losing intelligence using advanced A product team asks for a 2x speedup on a Llama 3 70B endpoint, and forbids Connect on LinkedIn: linkedin.com/in/shawhintalebi/ Here, I discuss 3 ways to do model
Llm Compression Explained Quantization Pruning For Faster Ai.pdf
What is the most accurate information about Llm Compression Explained Quantization Pruning For Faster Ai?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Compression Explained Quantization Pruning For Faster Ai.
Why is Llm Compression Explained Quantization Pruning For Faster Ai trending right now?
Interest in Llm Compression Explained Quantization Pruning For Faster Ai has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Llm Compression Explained Quantization Pruning For Faster Ai?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Llm Compression Explained Quantization Pruning For Faster Ai updated?
We regularly update our database with the latest information, media, and analysis related to Llm Compression Explained Quantization Pruning For Faster Ai.