Background on Llm Inference Optimization Async Continuous Batching With Cuda Streams
Looking for the latest information on Llm Inference Optimization Async Continuous Batching With Cuda Streams? We've researched comprehensive data, records, and insights about Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Important Facts
Explore the main sources for Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Developments
Stay updated on Llm Inference Optimization Async Continuous Batching With Cuda Streams's newest achievements.
Continuous Batching in LLMs Explained: Fast LLM Inference & Serving (vLLM, TensorRT-LLM)
Continuous Batching Explained | vLLM vs TGI vs SGLang | LLM Inference Optimization & PagedAttention
L-52: Continuous batching – vs Static Batching for LLM Inference #llm #inference
Mastering LLM Inference Optimization From Theory to Cost Effective Deployment: Mark Moyou
Building an LLM Inference Engine in C++ from scratch: Static & Continuous Batching Explained Easily!
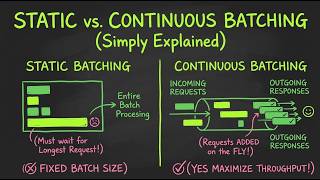
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
LLM Inference Optimization: How Quantization, Batching & Distillation Make AI Faster
The GPU Is Mostly Waiting: Continuous Batching, Explained
How to Scale LLM Applications With Continuous Batching!
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 19, 2026
Final Thoughts
For 2026, Llm Inference Optimization Async Continuous Batching With Cuda Streams remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Hugging Face explains how to make How does ONE GPU serve hundreds of people at once? This is the full story of vLLM, built from zero: why generating text is a ... Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... How can a single GPU serve 50 users at virtually the same speed as one? In this video, we break down why naive static Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... Deploying Large Language Models into production requires solving real-world latency, memory, and cost bottlenecks. In this video, you'll learn the modern techniques behind Welcome back to our video series on building a smaller VLLM for LLama 3.2 1B model. Today we go over When a GPU runs a language model, it spends most of its time waiting for memory, not doing math. This video explains, from the ...
Llm Inference Optimization Async Continuous Batching With Cuda Streams.pdf
What is the most accurate information about Llm Inference Optimization Async Continuous Batching With Cuda Streams?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Why is Llm Inference Optimization Async Continuous Batching With Cuda Streams trending right now?
Interest in Llm Inference Optimization Async Continuous Batching With Cuda Streams has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Llm Inference Optimization Async Continuous Batching With Cuda Streams?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Llm Inference Optimization Async Continuous Batching With Cuda Streams updated?
We regularly update our database with the latest information, media, and analysis related to Llm Inference Optimization Async Continuous Batching With Cuda Streams.