Overview on Llm Parallel Processing Powerful Training Strategies
Looking for the latest information on Llm Parallel Processing Powerful Training Strategies? We've gathered comprehensive data, records, and insights about Llm Parallel Processing Powerful Training Strategies.
Key Details
Explore the primary sources for Llm Parallel Processing Powerful Training Strategies.
History
Stay updated on Llm Parallel Processing Powerful Training Strategies's newest achievements.
Scaling LLM Training to Thousands of GPUs | Nouamane Tazi, HuggingFace |
06: Scaling Up, Training and Parallelism – Large Language Models (NUS CS6101 NUS.WING)
How DDP works || Distributed Data Parallel || Quick explained
Stanford CS336 Language Modeling from Scratch | Spring 2025 | Lecture 7: Parallelism 1
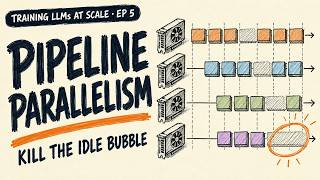
Expert Parallelism: 1 Trillion Params, One Sliver Per Token | Training LLMs at Scale #6
CMU Advanced NLP Fall 2025 (18): Parallelism and Distributed Training
EfficientML.ai Lecture 11 - TinyEngine and Parallel Processing (MIT 6.5940 Fall 2026)
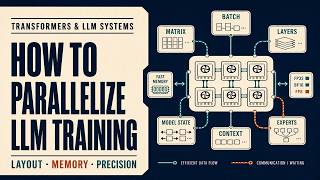
How LLM Training Actually Scales: Parallelism, FlashAttention & Precision
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 21, 2026
Summary
For 2026, Llm Parallel Processing Powerful Training Strategies remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
We are excited to feature Nouamane Tazi, Research Engineer at Hugging Face, discussing "Scaling Part 2 of 5 in the “5 Essential For more information about Stanford's graduate programs, visit: online.stanford.edu/graduate-education October 17, 2025 ... 00:00 Week 05 Kahoot! (Winston/Min) 15:00 LECTURE START - Scaling Laws (Arnav) 33:45 Scaling with FlashAttention (Conrad) ... Discover how DDP harnesses multiple GPUs across machines to handle larger models and datasets, accelerating the This lecture (by Sean Welleck) for CMU CS 11-711, Advanced NLP covers: - Basics of EfficientML.ai Lecture 11 - TinyEngine and Free newsletter: multiagentacademy.substack.com/ Buying faster accelerators does not guarantee a faster
Llm Parallel Processing Powerful Training Strategies.pdf
What is the most accurate information about Llm Parallel Processing Powerful Training Strategies?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Parallel Processing Powerful Training Strategies.
Why is Llm Parallel Processing Powerful Training Strategies trending right now?
Interest in Llm Parallel Processing Powerful Training Strategies has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Llm Parallel Processing Powerful Training Strategies?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Llm Parallel Processing Powerful Training Strategies updated?
We regularly update our database with the latest information, media, and analysis related to Llm Parallel Processing Powerful Training Strategies.