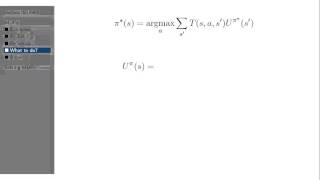Looking for the latest information on Mdps The Value Function? We've researched comprehensive data, records, and insights about Mdps The Value Function.
Main Features
Explore the main sources for Mdps The Value Function.
Developments
Stay updated on Mdps The Value Function's latest milestones.
Markov Decision Process (MDP) - 5 Minutes with Cyrill
Lecture 2: Key Concepts in RL (MDPs, Policies, Value Functions)
ECE493 - Sections 3.5 to 3.6 - MDP Value Functions
Markov Decision Processes 1 - Value Iteration | Stanford CS221: AI (Autumn 2019)
Model Based Reinforcement Learning: Policy Iteration, Value Iteration, and Dynamic Programming
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 21, 2026
Future Outlook
For 2026, Mdps The Value Function remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
How does reinforcement learning find the best decision for every possible state? In this video, we explore Once the problem is formulated as an MDP, finding the optimal policy is more efficient when using For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/ai Andrew ... Dive into the core concepts of Reinforcement Learning! This video breaks down Markov Decision Processes ( Mastering Reinforcement Learning 0.1 is the probability of transitioning to that state and then the reward again is going to be zero and the This video is part of the Udacity course "Reinforcement Learning". Watch the full course at udacity.com/course/ud600. Deterministic route finding isn't enough for the real world - Nick Hawes of the Oxford Robotics Institute takes us through some ... So in a bit more detail with these Here we introduce dynamic programming, which is a cornerstone of model-based reinforcement learning. We demonstrate ...