Looking for the latest information on Optimizing Llm Inference Requests? We've gathered comprehensive data, records, and insights about Optimizing Llm Inference Requests.
Important Facts
Explore the primary sources for Optimizing Llm Inference Requests.
History
Stay updated on Optimizing Llm Inference Requests's latest milestones.
Faster LLMs: Accelerate Inference with Speculative Decoding
What is Prompt Caching Optimize LLM Latency with AI Transformers
LLM Inference Optimization Explained — From 8 Tokens/sec to 50+
Optimize LLM inference with vLLM
Optimizing CPU LLM Inference in PyTorch: Lessons From VLLM - Crefeda Rodrigues & Fadi Arafeh
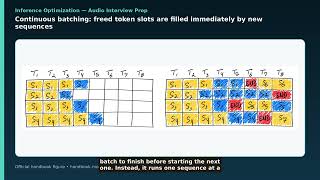
Continuous Batching and LLM Optimization | Scaling High-Performance AI Inference Systems | Uplatz
Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization by Legare Kerrison
[VDBUH2026] Abdel Sghiouar - Optimizing LLM Inference for the Rest of Us
LLM Inference Handbook: 06 Inference Optimization
Understanding the LLM Inference Workload - Mark Moyou, NVIDIA
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 16, 2026
Summary
For 2026, Optimizing Llm Inference Requests remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Our new book club series is about Don't miss out! Join us at our next KubeCon + CloudNativeCon events in Mumbai, India (18-19 June, 2026), Yokohama, Japan ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Why does a 70B language model crawl at 8 tokens per second on one setup, then feel instant on another? The difference is ... Ready to serve your large language models faster, more efficiently, and at a lower cost? Discover how vLLM, a high-throughput ... Welcome to Uplatz, where we explore the technologies, business models, economic shifts, and engineering concepts shaping the ... Download the source code from here: onepagecode.substack.com/ Not every organization operates with the hyperscale resources of Anthropic, Google, or OpenAI. For the majority of businesses ...