Looking for the latest information on Pruning And Model Compression? We've researched comprehensive data, records, and insights about Pruning And Model Compression.
Key Details
Explore the primary sources for Pruning And Model Compression.
Latest News
Stay updated on Pruning And Model Compression's latest milestones.
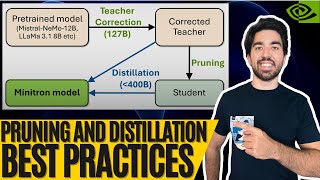
Pruning and Distillation Best Practices: The Minitron Approach Explained
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
Adversarial Robust Model Compression using In-Train Pruning
[Paper Review] You Only Prune Once: Designing Calibration-Free Model Compression
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
AI Model Efficiency Toolkit (AIMET) Channel Pruning compression
Compressing Neural Networks for Embedded AI: Pruning, Projection, and Quantization
SlimQwen: Optimizing Large MoE Model Compression Through Pruning and Distillation
EfficientML.ai Lecture 3 - Pruning and Sparsity (Part I) (MIT 6.5940, Fall 2023)
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 21, 2026
Summary
For 2026, Pruning And Model Compression remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io Four techniques to optimize the speed ... Ever wonder how powerful AI models can run on your smartphone? The secret is Build Your First Scalable Product with LLMs: academy.towardsai.net/courses/beginner-to-advanced-llm-dev?ref=1f9b29 ... sites.google.com/view/saiad2021/home. Sengupta, A., Chaudhary, S., & Chakraborty, T. (2025). You only Introducing the SlimQwen framework for efficiently