Reinforcement learning comparison - Sarsa vs. Q-learning - Cliff walking
SARSA Reinforcement Learning | On Policy Learning for Smarter RL Agents
Reinforcement-Learning : The Sarsa Algorithm in Python
RL Chapter 6 Part3 (TD methods for control: SARSA, Q-learning)
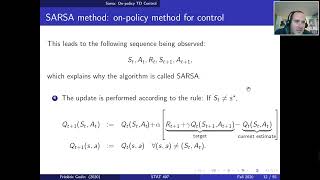
RL 8: Value function approach - Temporal Difference Reinforcement Learning - SARSA Algorithm
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 20, 2026
Future Outlook
For 2026, Rl1 6 Sarsa Algorithm remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this video, we explore two important Reinforcement Learning In today's lecture we cover the basic differences between two RL TD-based We build a control loop using TD estimation. This enables us to learn the optimal policy while we are playing with it. The final ... buymeacoffee.com/pankajkporwal ☕ Code : drive.google.com/open?id=1Wb2qDk_6u6SIjKTDbqfwdK9-ZFN0aOjw Abonnez-vous pour rester informé des ... This lecture introduces temporal difference (TD) methods for control problem. The on-policy Value function approach - Temporal Difference Reinforcement Learning (TD learning) -