Looking for the latest information on Tripleo Compute Node Scale Up? We've compiled comprehensive data, records, and insights about Tripleo Compute Node Scale Up.
Core Information
Explore the key sources for Tripleo Compute Node Scale Up.
Recent Updates
Stay updated on Tripleo Compute Node Scale Up's latest milestones.
Scale Out Networks and Scale Up Architectures with CPO
Lessons Learned from a Large Scale OpenStack Deployment with Tripleo
Scaling your Node.js app using the cluster module
TripleO Network Configuration
AKS Autoscaling Tutorial | Auto Scale Nodes (Live Demo)
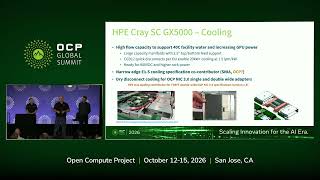
Scaling OCP for Supercomputing The Cray GX Infrastructure
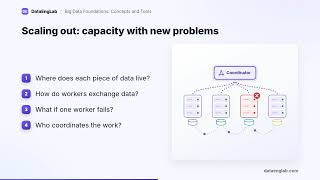
Scale up vs Scale out
Scale Up and Scale Out Ealstic with ROBIN Platform
Scale-up and Scale-out challenges for disaggregated infrastructure
Kubernetes autoscaler - scaling up nodes - shown
Virtual nodes to auto-scale applications on Kubernetes
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 17, 2026
Summary
For 2026, Tripleo Compute Node Scale Up remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this video, we're adding a new In this video, we take a look at the We've been using these terms for years - but in one of them has quietly changed its meaning. In this As an administrator, I want to configure Special thanks to our 2020 Open Infrastructure Summit sponsors for making the event possible: Canonical (Ubuntu), Huawei, ... In this tutorial for the "cluster" module of In this video, we look at configuring networks for our AKS Autoscaling Tutorial | Auto Javier Izquierdo Director, HPC Platform Engineering - HPE Brian Purcell Senior Distinguished Technologist - HPE The HPE Cray ... A bigger machine or more machines? When a data job outgrows its server, this is one of the most common decisions in data ... Scale on-demand No need to create IT tickets wait for days to Presented by Siamak Tavallaei (Independent) An Exa-FLOP AI/ML/HPC system requires 256 xPUs at 4 Tera-FLOP each. Such an ... Let's see a demo application using ServiceMonitor for Prometheus, a HPA, and a custom container that will count the instances of ...