KV Cache in LLM Inference - Complete Technical Deep Dive
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 19, 2026
Final Thoughts
For 2026, 2 2 Kv Cache remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
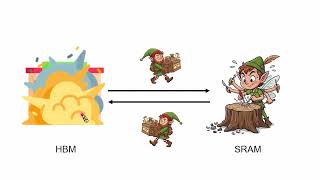
Learn more about LLM inference here → ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ... Solidigm: solidigm.com/products/data-center.html Parts: Vision3 E1.S Cage ... 影片剪輯:李一駿助教課程投影片都可以在公開的課程網頁上找到 speech.ee.ntu.edu.tw/~hylee/ml/2026-spring.php 先備 ... In this deep dive, we'll explain how every modern Large Language Model, from LLaMA to GPT-4, uses the To produce one word, a language model has to look back at every word that came before it and run the entire stack of attention ... Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The This is the second video of the series where I go over in great detail what the I've remade the video: youtube.com/watch?v=C_RnEVRvq7Y *Don't the Sound Effect? TurboQuant... the next big jump in local AI isn't a faster chip, but a different kind of compression. 🛡️Go to ... Lecture 3 of the Inference Engineering series going under the hood of modern LLM inference. In this lecture, we move from the ... 在硅谷采访100个有意思的人,这里是月球大叔。今天我们请到了Jiang Junchen,先恭喜junchen这个月刚拿到了2000多万美金的 ...