What is Prompt Caching Optimize LLM Latency with AI Transformers
Give Me 20 Minutes, and the KV Cache Will Click Forever
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 19, 2026
Conclusion
For 2026, Kv Cache Explained remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
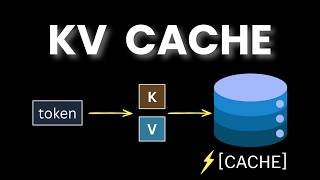
Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The Learn more about LLM inference here → ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ... To produce one word, a language model has to look back at every word that came before it and run the entire stack of attention ... Ever wonder how even the largest frontier LLMs are able to respond so quickly in conversations? In this short video, Harrison Chu ... I've remade the video: youtube.com/watch?v=C_RnEVRvq7Y *Don't the Sound Effect? Blog: cefboud.com/ X X: x.com/moncef_abboud 0:00 Introduction to LLM Inference 0:24 Ingredient 1: Model Weights ... Ever wondered how large language models GPT respond so fast without recomputing everything from scratch? In this video, I ... LLM系列图文教程: xuanyuancode.com/ai-llm 视频中的动画使用 svganimate.ai 制作. Ready to become a certified watsonx Generative AI Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Don't SFX? youtu.be/Z60RipDmEvw Not familiar with attention? youtu.be/eo1BZCcFYvI Not familiar with ...