About of Continuous Batching Optimize Llm Serving Throughput And Latency
Looking for the latest information on Continuous Batching Optimize Llm Serving Throughput And Latency? We've compiled comprehensive data, records, and insights about Continuous Batching Optimize Llm Serving Throughput And Latency.
Main Features
Explore the key sources for Continuous Batching Optimize Llm Serving Throughput And Latency.
Recent Updates
Stay updated on Continuous Batching Optimize Llm Serving Throughput And Latency's newest achievements.
L-52: Continuous batching – vs Static Batching for LLM Inference #llm #inference
How to Scale LLM Applications With Continuous Batching!
LLM Optimization Lecture 5: Continuous Batching and Piggyback Decoding
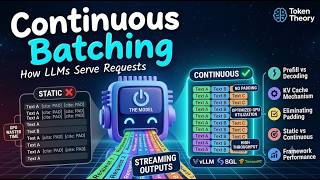
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
Continuous Batching in LLMs Explained: Fast LLM Inference & Serving (vLLM, TensorRT-LLM)
How KV Cache Speeds Up LLMs for Faster AI Models on GPUs
Continuous Batching and LLM Optimization | Scaling High-Performance AI Inference Systems | Uplatz
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 18, 2026
Summary
For 2026, Continuous Batching Optimize Llm Serving Throughput And Latency remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this video, we dive deep into Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver Ready to become a certified watsonx Generative AI Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Getting a model to run and getting it to handle a hundred users are different problems. Without touching the weights or changing a ... Ever wondered how ChatGPT, DeepSeek, Claude, Gemini, and other Large Language Models (LLMs) can Hugging Face explains how to make Welcome to Uplatz, where we explore the technologies, business models, economic shifts, and engineering concepts shaping the ...
Continuous Batching Optimize Llm Serving Throughput And Latency.pdf
What is the most accurate information about Continuous Batching Optimize Llm Serving Throughput And Latency?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Continuous Batching Optimize Llm Serving Throughput And Latency.
Why is Continuous Batching Optimize Llm Serving Throughput And Latency trending right now?
Interest in Continuous Batching Optimize Llm Serving Throughput And Latency has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Continuous Batching Optimize Llm Serving Throughput And Latency?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Continuous Batching Optimize Llm Serving Throughput And Latency updated?
We regularly update our database with the latest information, media, and analysis related to Continuous Batching Optimize Llm Serving Throughput And Latency.