Looking for the latest information on Direct Preference Optimization Dpo? We've gathered comprehensive data, records, and insights about Direct Preference Optimization Dpo.
Key Details
Explore the key sources for Direct Preference Optimization Dpo.
History
Stay updated on Direct Preference Optimization Dpo's latest milestones.
Direct Preference Optimization (DPO) | Paper Explained
Aligning LLMs with Direct Preference Optimization
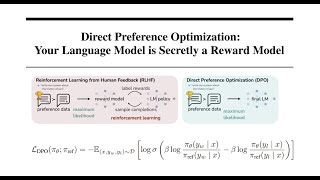
Direct Preference Optimization (DPO): Your Language Model is Secretly a Reward Model Explained
Direct Preference Optimization (DPO) Explained: Aligning LLMs Without Reinforcement Learning
Direct Preference Optimization Beats RLHF (Explained Visually), how DPO works
Direct Preference Optimization (DPO) and Friends | Post-Training Course, Lecture 6
Fine-tuning LLMs on Human Feedback (RLHF + DPO)
Direct Preference Optimization (DPO) Explained | in 2 Minutes
LLM Fine-Tuning 16: Preference Alignment & Preference Training in LLMs with RLHF, RLAIF, DPO, LoRA
Direct Preference Optimization (DPO)
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 16, 2026
Summary
For 2026, Direct Preference Optimization Dpo remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
... Stanford CS234 Reinforcement Learning I Offline RL 2 and Guest Lecture on In this workshop, Lewis Tunstall and Edward Beeching from Hugging Face will discuss a powerful alignment technique called ... Paper found here: arxiv.org/abs/2305.18290. The standard Reinforcement Learning from Human Feedback (RLHF) pipeline—involving reward model training and complex ... In this video, I break down DeepSeek's Group Relative Policy In this lecture we cover one of the neatest, and most pedagogical, pieces of post-training: Connect on LinkedIn: linkedin.com/in/shawhintalebi/ Here, I discuss how to use reinforcement learning to fine-tune ... How do modern AI systems learn human Get the Dataset: huggingface.co/datasets/Trelis/hh-rlhf-