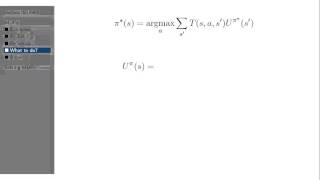Background to Lecture 23b Policy And Value Function
Looking for the latest information on Lecture 23b Policy And Value Function? We've researched comprehensive data, records, and insights about Lecture 23b Policy And Value Function.
Core Information
Explore the primary sources for Lecture 23b Policy And Value Function.
Developments
Stay updated on Lecture 23b Policy And Value Function's latest milestones.
Policy, Value Function and Model Explained
Lecture 17 - MDPs & Value/Policy Iteration | Stanford CS229: Machine Learning Andrew Ng (Autumn2018)
Value Functions - Fundamentals of Reinforcement Learning
RL @ ECE-UofT - Lecture 02: MDPs and Bellman
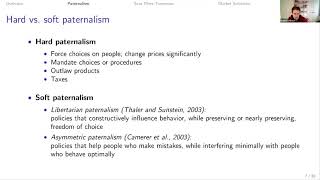
Lecture 23: Policy with Behaviorial Agents
Policy Evaluation vs. Control - Fundamentals of Reinforcement Learning
Lecture 3 - Policy and Value Iteration
Q function and Value Function Concepts | Reinforcement Learning Algorithms
L3 Policy Gradients and Advantage Estimation (Foundations of Deep RL Series)
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 20, 2026
Conclusion
For 2026, Lecture 23b Policy And Value Function remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
We derive the Bellman Optimality equation. This equation enables us to compute the optimal 0.1 is the probability of transitioning to that state and then the reward again is going to be zero and the In this video, you will learn Major Components of an Reinforcement Learning Agent, including For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/ai Andrew ... Reach out to us :) truetheta.io Part two of a six part series on Reinforcement Learning. We discuss the Bellman Equations, ... We define mathematically the notions of MIT 14.13 Psychology and Economics, Spring 2020 Instructor: Prof. Frank Schilbach View the complete course: ... Welcome to our insightful discussion on two critical concepts in the world of reinforcement learning: the