Introduction of Lecture 33 Optimizing Reduction Kernels Contd
Looking for the latest information on Lecture 33 Optimizing Reduction Kernels Contd? We've gathered comprehensive data, records, and insights about Lecture 33 Optimizing Reduction Kernels Contd.
Key Details
Explore the key sources for Lecture 33 Optimizing Reduction Kernels Contd.
Optimized Reduction Kernel Explained | CUDA Warp and Block Reduction
Lecture 26: Memory Access Coalescing (Contd.)
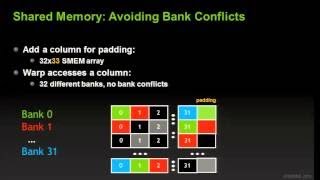
CUDA Part F: Kernel Optimizations: Shared Memory Accesses; Peter Messmer (NVIDIA)
KernelAgent: Hardware-Guided GPU Kernel Optimization via... Kaiming Cheng, Jack Khuu & Laura Wang
Lecture 37 : Kernel Fusion, Thread and Block Coarsening (Contd.)
Lecture 25: Memory Access Coalescing (Contd.)
Lecture 23: Memory Access Coalescing (Contd.)
Lecture 17: Warp Scheduling and Divergence (Contd.)
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 16, 2026
Future Outlook
For 2026, Lecture 33 Optimizing Reduction Kernels Contd remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Sorting bitinic sequence, All Prefix Sum , Inclusive and exclusive scan. Steel inclusive scan, Prefix Sum Implementation, Blelloch Scan Algorithm and Implementation. Comparator, Sorting subproblem, Bitonic Sort Parallel Implementation. Sorting, Sorting Networks, Bitonic Sort Serial Implementation, Recursion. Transpose: Resolving Shared Memory Bank Conflicts, Memory Padding. Programming for GPUs Course: Introduction to OpenACC 2.0 vesves CUDA 5.5 - ember 4-6, 2017. Programming for GPUs ... Don't miss out! Join us at our next KubeCon + CloudNativeCon event in Salt Lake City, United States (Nov 9–12, 2026). Connect ... Inner and Inter Block Fusion - example, advantage and disadvantages. Transpose Using Shared Memory, shared memory load transactions; store transactions. Transpose Operation: Naive Row and Naive Col Implementations.
What is the most accurate information about Lecture 33 Optimizing Reduction Kernels Contd?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Lecture 33 Optimizing Reduction Kernels Contd.
Why is Lecture 33 Optimizing Reduction Kernels Contd trending right now?
Interest in Lecture 33 Optimizing Reduction Kernels Contd has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Lecture 33 Optimizing Reduction Kernels Contd?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Lecture 33 Optimizing Reduction Kernels Contd updated?
We regularly update our database with the latest information, media, and analysis related to Lecture 33 Optimizing Reduction Kernels Contd.