Looking for the latest information on Training With Domain Randomization? We've researched comprehensive data, records, and insights about Training With Domain Randomization.
Important Facts
Explore the key sources for Training With Domain Randomization.
Developments
Stay updated on Training With Domain Randomization's newest achievements.
Training with Domain Randomization
Research at NVIDIA: Structured Domain Randomization
Continual Domain Randomization
Domain Randomization
Structured Domain Randomization
ROS Developers LIVE-Class #41: Domain randomization with ROS, Gazebo and Fetch | part 2
Robust RL with Domain Randomization and Adaptation
M17V04 Domain randomization
Domain Randomization for Transferring Deep Neural Networks from Gazebo to Real World Using ROS
CS 285: Lecture 21, Transfer Learning, Part 3
Deep Drone Racing: From Simulation to Reality with Domain Randomization
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 16, 2026
Final Thoughts
For 2026, Training With Domain Randomization remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
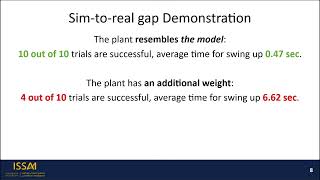
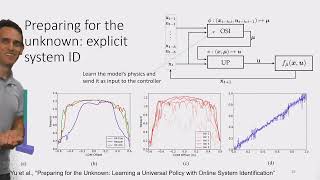
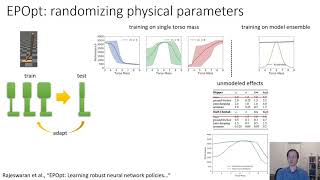
In this series, we explore using reinforcement learning algorithms (RL) to have a robot learn to balance on its own. We will deploy ... Course Instructor: Pieter Abbeel Guest Lecturer: Josh Tobin Course Website: ... In this class, we are going to see how to reproduce the results of the famous paper " To help make deep learning more accessible, researchers from NVIDIA have introduced a structured Supplementary video for the "Continual On our approach to randomizing objects, texture and other scene components within the realistic values. This Live Class is about how to create datasets from simulations and how to manage them. We are going to see: ▸ How to create ... The video demonstrates our solution of the sim-to-real gap of reinforcement learning policy caused by a mismatch of simulated ... We have replicated the results of the amazing paper by OpenAI " Dynamically changing environments, unreliable state estimation, and operation under severe resource constraints are ...