Introduction on Transform Vector Quantization Part 1
Looking for the latest information on Transform Vector Quantization Part 1? We've gathered comprehensive data, records, and insights about Transform Vector Quantization Part 1.
Core Information
Explore the primary sources for Transform Vector Quantization Part 1.
Developments
Stay updated on Transform Vector Quantization Part 1's latest milestones.
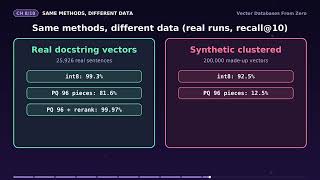
Vector Databases : 8 - Vector Quantization: Shrink Vectors 4x to 32x, Real Recall
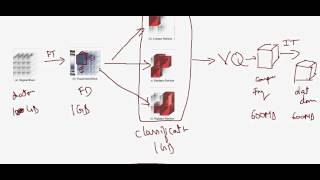
Transform Vector Quantization Part-2
Vector Quantization Part 1
CVPR2024 Codebook Transfer with Part-of-Speech for Vector-Quantized Image Modeling
VQ-VAE Explained: Vector Quantization, Codebook and Straight-Through Estimator | Generative AI 26
KV Cache Quantization Explained: How to Fit 4x More Context
2504.19874 - TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
vector quantization
PolarQuant: Polar Coordinate Transformation for KV Cache Quantization
Vector Quantization Part-2
Vector Quantization: Rounding to Codebook Entries
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 29, 2026
Conclusion
For 2026, Transform Vector Quantization Part 1 remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In the previous video I was talking about Unaligned 2D to 3D Translation with Conditional this is a video for CVPR2024 Codebook Transfer with A VAE whose codes are symbols from a learnable vocabulary: this video builds the At long context the KV cache, not the weights, decides how many users a GPU can serve. Llama 3.1 8B stores 128 KB of keys and ... lossy data compression technique. These podcast introduce QJL and TurboQuant, two advanced mathematical frameworks designed to compress the Key-Value ...