Looking for the latest information on Cl25 Clsetkernelarg? We've compiled comprehensive data, records, and insights about Cl25 Clsetkernelarg.
Key Details
Explore the key sources for Cl25 Clsetkernelarg.
Developments
Stay updated on Cl25 Clsetkernelarg's newest achievements.
CL#13[ clBuildProgram ]
16GB VRAM (+RAM): Local AI Coding Setup
How To Run Opencl kernel Part 2 | #compilersutra #opencl
OpenCL Host Side Programming: Context, queues, memory objects, etc.
Zig Memory Layout is Better Than C
Lean-QwenFlash: Qwen3.8-Flash-Next (125B Model) on 8GB of RAM
Why Fewer CPU Threads Made YOLO 2x Faster (ONNX Runtime)
Is NVIDIA Nerfing Your GPU on Purpose
Как сделать WEB Сервер на C++ GPU 5
Qwen 3.8 27B Physics Test on 12GB and 16GB VRAM
Finally, a Fast Coding AI That Runs Locally (Flint)
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 31, 2026
Conclusion
For 2026, Cl25 Clsetkernelarg remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
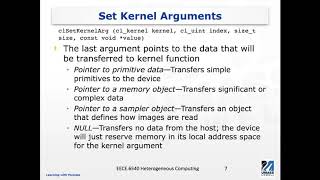
Loading kernel function arguments and calling a kernel function are two distinct steps within the OpenCL API. The first step ... clEnqueueNDRangeKernel Manual Page ... clCreateCommandQueueWithProperties Manual Page ... [BEGIN:Transcript] Optional build options, unless you are following along. Call CL build program with your program object, the ... If you have a 16GB VRAM graphics card and a gaming PC, what model should you run? It depends on your system RAM. 32GB or ... Beginner to Expert Guide: Running Your First OpenCL Hello World Program Learn OpenCL from scratch — Ideal for C/C++ ... OpenCL Host Side Programming: Context, queues, memory objects, etc. Try SerpApi for free with 250 search credits: serpapi.com/?utm_source=youtube&utm_campaign=codeguild_october_2026 ... Lean-QwenFlash runs Qwen3.8-Flash-Next, a 125-billion-parameter mixture-of-experts model, with only 8 GB of system RAM and ... Why Fewer CPU Threads Made YOLO 2x Faster (ONNX Runtime) In Ultralytics' benchmark, limiting PyTorch to two threads cut the ... Viral posts are sweeping the tech community claiming that NVIDIA sold millions of RTX 30-series graphics cards with half of their ... Skype MisterTimur пишется слитно Поддержать канал donationalerts.ru/r/timurabdulov Исходный код ... Qwen 3.8 27B gets a hexagon physics test, run on two VRAM caps. 12 GB cap (IQ3_S quant, ISTA-DASLab): the page freezes ... Recursive just launched Flint, an open-weight coding AI built from scratch in four months that claims over 125 tokens a second on ...